
Faster Dashboard Refresh, Same Response Time: What Is Missing?
Many factories have upgraded their dashboards from hourly refreshes to minute-level updates, with more prominent alarm colors. However, after an anomaly occurs, the team still has to ask in the group chat who is handling it, and maintenance arrives only to find missing spare parts, while quality issues continue waiting for the supervisor's decision. The data is more real-time, but the shop-floor actions have not sped up.
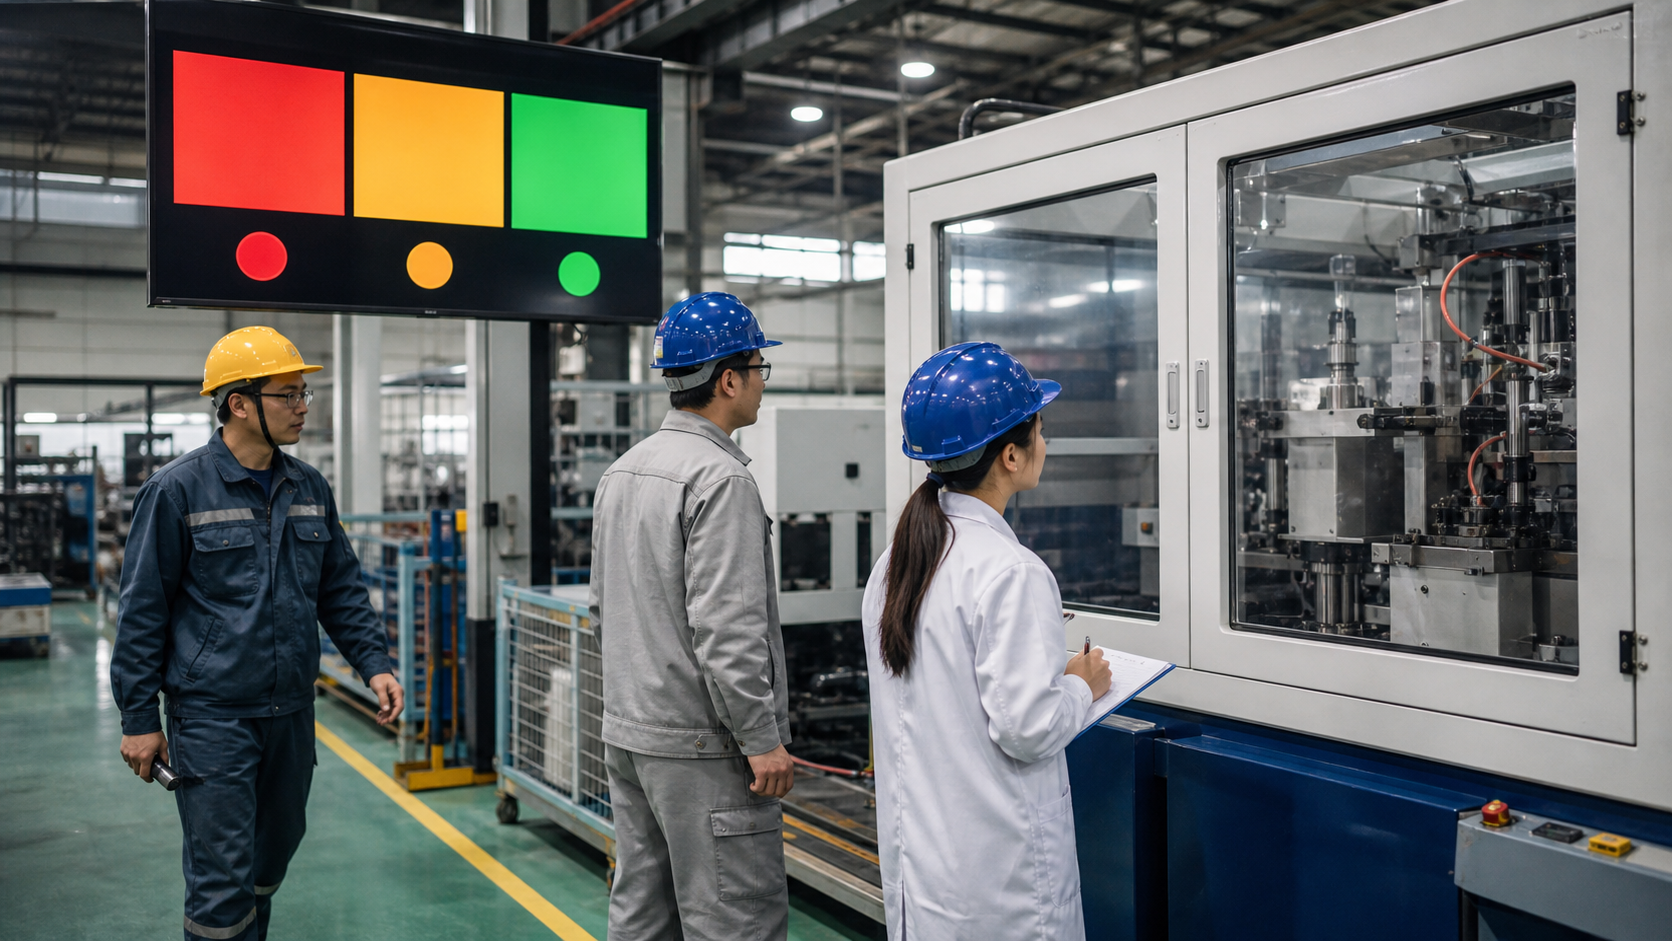
Why Is On-the-Floor Response Not Getting Faster Despite Faster Dashboard Refresh?
Many factories have upgraded their dashboards from hourly refreshes to minute-level updates, with more prominent alarm colors. However, after an anomaly occurs, the team still has to ask in the group chat who is handling it, and maintenance arrives only to find missing spare parts, while quality issues continue waiting for the supervisor's decision. Data is more real-time, but on-the-floor actions have not accelerated.
This approach applies to mid-sized growing factories. Factory owners, plant managers, and production supervisors need to understand: dashboards only inform 'what happened,' not 'who takes what action within what timeframe.' Real-time data will not automatically translate into responsiveness without this.
Step One: Identify Who Actually Owns the Response
Putting all equipment, quality, material, and delivery anomalies on one dashboard with red color coding can quickly lead to visual fatigue. A more practical issue is that red only indicates severity without specifying the responsible role or the priority of handling.
First, categorize anomalies by impact level: safety and quality disruptions should be immediately stopped, delivery risks enter time-bound handling, and general fluctuations enter trend observation. Each level should be assigned a first-contact position to ensure someone confirms the anomaly immediately, rather than waiting for the most knowledgeable person to pass by.
Step 2: Break Down the Five-Stage Waiting Process
When someone clicks to acknowledge an issue, it only proves the message was seen. What needs to be separately tracked are the times for confirmation, arrival, diagnosis, resolution, and verification. If confirmation is quick but diagnosis is slow, urging the team is pointless; instead, the fault information and diagnostic support should be supplemented.
If resolution is fast but verification is delayed, the issue may lie in quality release or trial production conditions. Breaking down the total time allows management to determine whether to add personnel, parts, permissions, or simplify cross-departmental confirmations.
Step Three: Elevate Duplicate Exceptions
Dashboards often reward quick light-out responses but may not drive root cause resolution. A machine experiencing multiple short stops per day, each taking two minutes to recover, may appear responsive, but the repetition indicates that temporary fixes have not been converted into stable solutions.
When the same object and cause recur within a defined cycle, it should automatically escalate to a recurring issue, requiring documentation of temporary measures, root cause tasks, responsible parties, and verification dates. Without verification results, the color may change from red to yellow, but it cannot be directly reset to green.
Step 4: Connect the Minimum Action Closed Loop
Each anomaly should include at least six elements: affected object, impact, severity, initial owner, response deadline, and closure criteria. Ownership may be transferred after acknowledgment, but the transfer time and reason must be retained. Team leaders need authority to coordinate the response, specialist roles are responsible for technical conclusions, and the plant manager resolves cross-departmental boundaries.
Closure criteria must be specific. Equipment resuming operation does not equate to fault closure, nor does the absence of quality anomalies mean the root cause has been eliminated. Different anomalies should be defined with distinct evidence for trial operation, first-off inspection, material replenishment completion, or measure verification.
After a dashboard is launched for one week, avoid reporting on refresh frequency and screen count. Instead, review three key results: how many anomalies went unassigned, which segment had the longest wait time, and how many similar issues recurred. These three metrics reveal execution gaps more effectively than average response time.
The End Point of Real-Time Data Is Verifiable Action
The value of manufacturing data analysis lies in transforming information into actionable decisions. When data collection, analysis, and decision support are disconnected, even faster results may be too late to impact the shop floor.
Therefore, the order of dashboard development should be reversed: first define who is responsible for what and when it is considered complete, then determine which data to display and what colors to use. This way, each refresh drives action rather than merely repeating the presentation of problems.
The true maturity of a dashboard is not indicated by a screen that never shows red, but by the fact that red appears, someone takes responsibility, the process is traceable, the results are verifiable, and recurrence is escalated. Refresh speed is just the starting point; response closure reflects management capability.
Not all factories need to retrofit all dashboards at the same time. Factory owners can forward this checklist to shop floor supervisors and team leaders, starting with a category of stoppage anomalies for one week, then deciding on the next management action.
I am Huang Chaoxing, inventor of the TreeMES stack-light MES system. Follow me for continued analysis of shop-floor management and digital transformation trends in manufacturing.
